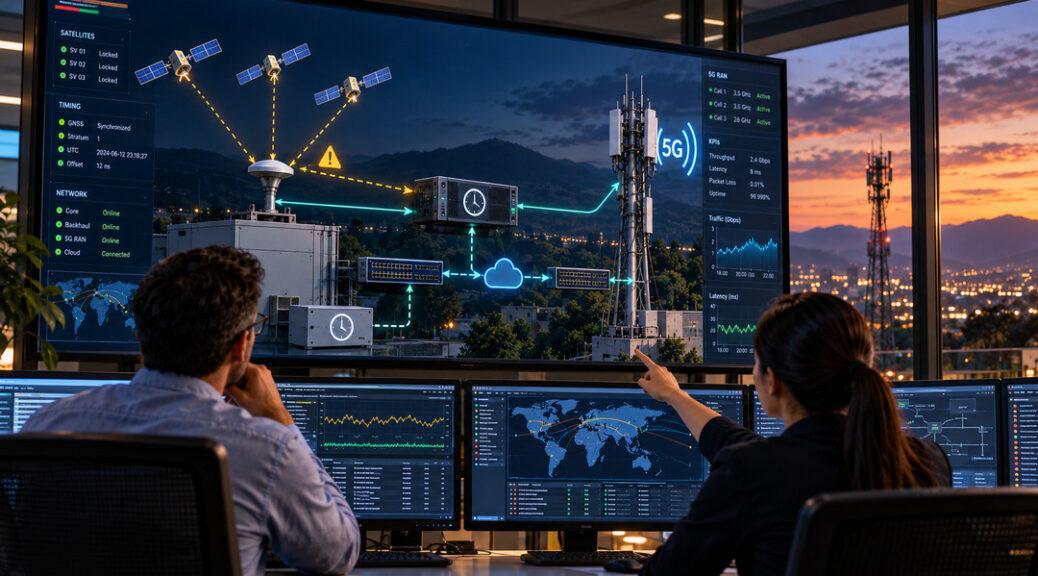
A 5G cell site can have electricity, an operational radio, and a working backhaul connection but still experience service problems because its timing reference has degraded.
That creates a network resilience problem that ordinary connectivity monitoring may not detect.
Mobile networks use precise synchronization to coordinate radio transmissions. Depending on the radio technology and deployment, synchronization errors can contribute to interference, degraded performance, and interrupted service.
Many telecommunications networks obtain their timing reference from Global Navigation Satellite Systems (GNSS), including GPS. Others distribute timing through terrestrial networks using technologies such as Precision Time Protocol (PTP).
Both approaches introduce dependencies that network operators need to understand.
Effective 5G timing resilience requires more than installing a second clock. Operators must verify the timing sources, identify shared failure points, measure clock performance, and establish what happens when the primary reference becomes unavailable.
The distinction is particularly important for private 5G networks, remote cellular sites, critical infrastructure communications, and networks supporting applications with strict synchronization requirements.
Why Accurate Timing Matters to 5G Networks
Telecommunications networks need different kinds of synchronization.
Frequency synchronization helps equipment operate at the intended frequency.
Phase and time synchronization coordinates events against a common timing reference.
These functions are related but not interchangeable.
In time-division duplex (TDD) mobile networks, uplink and downlink transmissions share a frequency band but occupy different time intervals.
Neighboring radio systems must coordinate their transmission periods appropriately to reduce interference.
If their timing relationships deteriorate, the resulting interference can affect network performance.
Other telecommunications applications also depend on accurate timing, including some industrial communications services and systems that require coordinated measurements.
Not every application has the same timing requirements.
An ordinary internet application may tolerate timing differences that would be unacceptable to a tightly synchronized radio network.
Consequently, a network design should identify the actual timing accuracy and continuity requirements of the equipment and services involved.
The engineering objective is not to obtain the most accurate clock available at any price.
It is to maintain the required accuracy under normal conditions and through the failure scenarios the operator intends to support.
GNSS Provides a Useful Reference but Creates an External Dependency
GNSS receivers can obtain highly accurate timing information from satellite navigation systems.
This makes satellite timing attractive for telecommunications infrastructure, including geographically distributed radio sites.
However, a GNSS receiver depends on signals arriving from outside the operator’s network.
Those signals can be affected by interference, equipment faults, antenna problems, environmental conditions, or deliberate manipulation.
The U.S. government’s guidance on resilient positioning, navigation, and timing emphasizes that critical infrastructure operators should prepare for potential signal disruptions and consider ways to verify the integrity of received information.
That guidance reflects a broader engineering concern: dependence on satellite timing can expose otherwise reliable infrastructure to failures outside the operator’s direct control.
A receiver reporting that it has lost satellite lock is one visible symptom.
Other problems can be harder to identify.
For example, a timing source might continue producing output while its accuracy deteriorates. A downstream network device may still receive synchronization messages without knowing whether the underlying reference remains trustworthy.
This is why monitoring only whether the GNSS receiver is online provides incomplete evidence.
Operators need to understand both the condition of the reference signal and the quality of the time delivered to the equipment that depends on it.
What the February 2026 ITU Timing Standard Establishes
On February 22, 2026, the International Telecommunication Union approved an updated version of Recommendation G.8275.1.
The ITU-T G.8275.1 recommendation addresses a telecommunications profile for Precision Time Protocol, based on IEEE 1588.
The February 2026 edition is listed as in force.
Its purpose is to define the PTP functions needed for interoperable phase, time, and frequency synchronization in telecommunications networks using full timing support.
Under this architecture, the transport network contains equipment capable of participating in the timing distribution process.
This can include PTP-aware network elements that help maintain synchronization along the path.
The important distinction is between transporting timing information and independently generating a trustworthy reference.
PTP can distribute timing information from a reference clock to other network devices.
It does not automatically make an inaccurate source correct.
If the primary reference becomes unreliable, a functioning PTP connection may continue carrying timing information whose accuracy no longer satisfies the network’s requirements.
Similarly, network equipment that supports PTP does not necessarily deliver identical accuracy in every configuration.
Performance depends on the clock architecture, implementation, network topology, traffic conditions, equipment capabilities, and other technical factors.
The 2026 ITU recommendation provides an interoperability framework for the specified telecommunications timing profile. Its publication should not be interpreted as proof that every deployed 5G network uses this architecture or that upgrading a PTP software component automatically improves timing resilience.
Backup Timing, Holdover, and Redundant References Are Different Protections
A resilient timing architecture can use several mechanisms.
However, each mechanism addresses a different operational problem.
A Secondary Timing Reference
An operator may configure an alternative reference that equipment can use when the preferred source becomes unavailable or unsuitable.
The value of that alternative depends on whether it can maintain the required timing performance and whether it shares important dependencies with the primary source.
Two independent-looking clock devices may still receive timing from the same upstream reference.
They might also depend on the same power supply, transport equipment, antenna installation, or vulnerable physical location.
Installing two devices therefore does not establish that the network has independent timing sources.
Local Clock Holdover
Holdover allows a clock to continue operating using its internal oscillator after the external reference is lost.
This can preserve useful synchronization temporarily.
But holdover accuracy is not unlimited.
The oscillator continues to experience frequency error, and the accumulated timing difference may grow while the external reference remains unavailable.
A simple hypothetical calculation shows why this matters.
Assume an oscillator maintains a constant fractional frequency error of one part per billion.
That is a frequency error of 0.000000001 relative to its nominal frequency.
Over one hour, the accumulated time error would be approximately:
3.6 microseconds.
After eight hours, the accumulated error would be approximately 28.8 microseconds.
These are illustrative calculations based on a constant frequency error. They are not measured results from any commercial clock.
Real holdover performance depends on oscillator quality, temperature, aging, calibration, previous operating conditions, and other design factors.
The useful question is therefore not simply whether equipment includes holdover capability.
It is how long that capability can maintain the specified timing accuracy under the conditions the operator needs to withstand.
Alternative Transport Paths
A secondary PTP transport path may protect against failure of a particular connection.
However, two timing paths can still share upstream equipment or depend on the same grandmaster reference.
This resembles physical redundancy problems in other telecommunications systems.
A network design must consider not only the number of paths but also the dependencies that could cause those paths to fail together.
A resilient design should identify whether alternative paths provide genuine independence from the intended failure scenario.
What 3GPP Requires Networks to Support
Timing resilience is also addressed in the specifications developed for 5G systems.
Section 6.36 of 3GPP TS 22.261, published through ETSI, covers 5G timing resiliency.
The publicly accessible Release 19 edition V19.12.0, published in October 2025, describes capabilities involving alternative timing sources, monitoring, and continued synchronization when a primary reference degrades or becomes unavailable.
Among other requirements, it addresses the system’s ability to support mechanisms that:
- Detect timing-source failures.
- Determine when a timing reference is no longer suitable.
- Identify degradation in network synchronization.
- Monitor different available timing sources.
- Support suitable alternative timing references.
- Report timing degradation and relevant timing errors.
These are system-level service requirements.
They should not be mistaken for evidence that every commercial 5G installation already includes every possible resilience mechanism.
The exact capabilities available to an operator depend on equipment support, implementation, configuration, and the requirements relevant to the deployment.
The specification is also maintained through successive releases and revisions. The cited October 2025 edition establishes the requirements described here, rather than representing every subsequent update.
The operational implication is straightforward.
A timing architecture should provide ways to detect degradation and respond appropriately, not merely continue operating until service problems become visible to customers.
How Telecom Operators Can Detect Timing Problems Earlier
Network operations centers commonly monitor link availability, traffic volumes, interface errors, and equipment alarms.
Timing resilience adds another layer of operational visibility.
Useful measurements can include the current timing source, its reported status, synchronization offset, oscillator state, reference changes, and indicators of timing quality.
Operators may also need to examine PTP message behavior and the condition of the transport network carrying synchronization information.
The most useful information depends on the equipment and architecture.
A practical monitoring process should distinguish three conditions.
The timing reference is unavailable. For example, equipment reports that its primary GNSS reference has been lost.
The timing reference is available but degraded. The equipment may still receive a signal, but the delivered timing quality no longer satisfies the intended requirements.
The network has changed timing sources. Equipment may be operating from a secondary reference or in holdover mode.
These conditions have different operational consequences.
A reference change may be expected behavior during a controlled maintenance activity.
Unexpected timing degradation affecting several neighboring sites may require more urgent investigation.
Monitoring should therefore connect source status with actual synchronization performance.
Where possible, timing measurements should be evaluated against an independent reference rather than relying only on the status reported by the clock being assessed.
For teams developing more comprehensive monitoring capabilities, NATEWIN’s guide to gNMI telemetry and network automation provides useful background on collecting structured operational data.
Model-driven telemetry can support monitoring where suitable device models expose timing information, but a generic interface counter does not establish clock accuracy. Equipment-specific timing measurements and validation remain necessary.
Remote 5G Sites Have Several Resilience Dependencies
Remote mobile sites introduce additional considerations.
An isolated site might use solar power, batteries, and satellite backhaul to reduce dependence on conventional infrastructure.
These arrangements can improve deployment flexibility and help operators address particular power and connectivity risks.
NATEWIN’s earlier coverage of portable solar-powered 5G infrastructure discusses the use of battery storage and satellite connections in remote deployments.
Timing should be evaluated as a separate dependency.
An off-grid site can have sufficient battery capacity while experiencing GNSS interference.
Likewise, satellite backhaul may remain available even when the local timing reference becomes unsuitable.
A satellite communications connection and a satellite navigation timing reference are not interchangeable services.
Operators should verify how the selected radio equipment obtains synchronization, which backup sources it supports, and how the system behaves when a reference becomes unavailable.
For a temporary or rapidly deployed site, this review can be especially important because the final equipment arrangement may differ from a conventional permanent installation.
The appropriate resilience design depends on the specific radio system, transport network, service requirements, and deployment conditions.
A Practical Timing Resilience Test Should Examine Actual Behavior
Telecommunications teams can assess timing resilience through controlled testing.
The objective should be to understand what the network does when an approved test environment simulates a reference failure or a change in synchronization conditions.
A useful engineering test plan can examine several stages.
Establish the Normal Timing State
Before testing, document the active timing source, equipment configuration, relevant clock specifications, and baseline synchronization measurements.
The baseline should describe the actual deployed architecture.
Evaluate Approved Failover Behavior
In a suitable laboratory or otherwise approved controlled environment, engineers can use supported equipment functions to test a reference transition.
They should record whether an alternative reference is selected, whether any interruption occurs, and whether the measured timing quality remains acceptable.
Actual procedures must follow vendor documentation and the organization’s safety and change-control requirements.
Examine Holdover Performance
A holdover test should compare observed behavior with the equipment’s applicable specifications.
The report should distinguish elapsed holdover time, measured timing error, environmental conditions, and any relevant configuration assumptions.
A short successful test does not demonstrate that a clock can sustain the same performance indefinitely.
Confirm Restoration Behavior
The return of the primary reference deserves attention.
Operators should verify whether the equipment resumes the intended timing source correctly and whether the transition produces unexpected synchronization changes.
Restoration is part of resilience, not an administrative detail after the initial failure has ended.
Testing should never involve unauthorized transmission of GNSS jamming or spoofing signals. Such activity can interfere with other users and may violate applicable law.
Approved simulation, vendor-supported equipment controls, and properly authorized laboratory methods are more suitable for routine operational validation.
Treat Timing Resilience as an Infrastructure Risk
The National Institute of Standards and Technology addresses positioning, navigation, and timing risks in its Foundational PNT Profile, NIST IR 8323 Revision 1.
Published January 31, 2023, the voluntary guidance provides a framework for identifying PNT dependencies, assessing threats, protecting systems, detecting problems, and preparing response and recovery activities.
It covers disruption or manipulation that may arise from natural events, accidental causes, or intentional actions.
The framework is broader than telecommunications, but its approach is useful for network operators.
A carrier can begin by identifying which equipment and services depend on external timing information.
It can then assess how those dependencies affect customer service, critical network functions, and recovery priorities.
The process should also identify the people responsible for timing-source management.
Radio engineers may understand synchronization requirements, while transport engineers manage PTP paths and operations teams monitor alarms.
Security teams may need to assess unauthorized changes or suspicious signal behavior.
If those responsibilities are handled separately without a shared incident procedure, an organization may struggle to determine why a timing problem is affecting services.
NIST’s guidance supports a risk-based approach rather than prescribing one clock design for every organization.
The Next Step Is to Verify the Timing Dependency Chain
Telecom organizations evaluating 5G timing resilience should concentrate on four practical questions.
First, which reference actually supplies time to the radio equipment?
Second, which shared infrastructure dependencies could affect both the primary and alternative references?
Third, how accurately can the equipment continue operating if the preferred reference disappears?
Fourth, can the operations team detect unacceptable timing degradation before it becomes a prolonged service problem?
These questions connect standards, engineering design, procurement, monitoring, and incident recovery.
They also help distinguish a product capability from an operationally verified result.
The updated ITU timing profile and existing 3GPP requirements provide technical foundations, but dependable service still depends on how equipment is integrated and tested.
For network operators, the most meaningful measure of timing resilience is not whether a backup clock appears on an equipment inventory.
It is whether the complete network can maintain the timing quality its services require, detect when that quality deteriorates, and recover through a documented and tested process.